Azure Databricks Medallion Data Platform
Architected a scalable Medallion Lakehouse on Azure Databricks and ADLS Gen2 with Delta Lake ACID guarantees.
Operational & Architectural Constraints
An analytical organization was struggling with fragmented CSV/Parquet dumps across object storage, leading to frequent schema drift, sluggish query performance on multi-gigabyte datasets, and unmanageable ETL scripts. Downstream analysts frequently questioned data validity due to inconsistent updates and unhandled pipeline partial failures.
System Design & Implementation
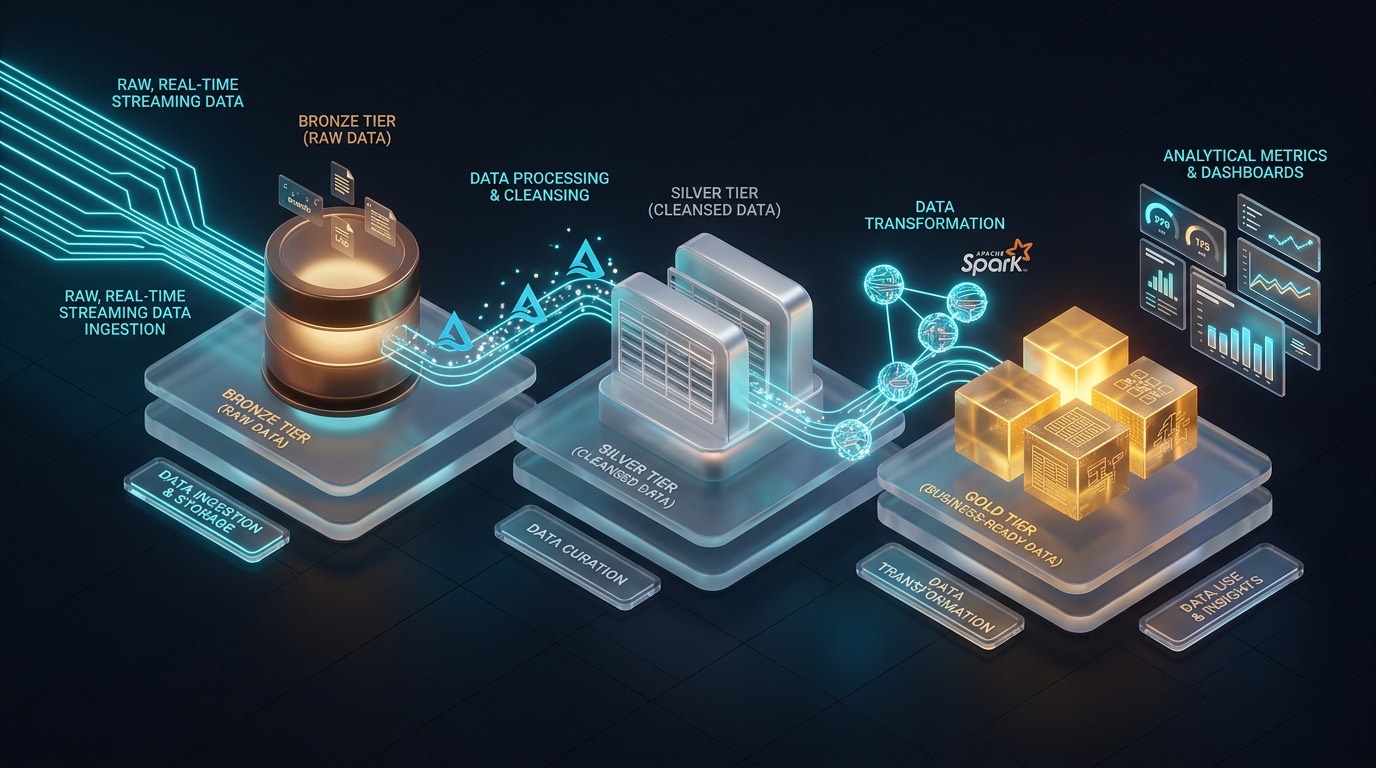
We engineered a modern Medallion Data Platform on Azure Databricks utilizing Delta Lake and Azure Data Lake Storage (ADLS Gen2). Raw events were ingested continuously into the Bronze layer preserving audit fidelity. Cleaned, deduplicated, and typed data was materialized into the Silver layer with schema validation. Finally, business-aggregated dimension and fact tables were generated in the Gold layer with Z-Ordering and liquid clustering for high-performance BI consumption.
Append-Only Delta Tables
Stores untransformed raw event dumps preserving 100% audit lineage.
Deduplicated Delta Tables
Enforces schema contracts, deduplicates surrogate keys, and filters invalid records.
Kimball Star Schemas
Pre-aggregated dimension and fact tables clustered via Delta Z-Ordering for sub-second queries.
End-to-End System Data Flow
System Data Flow: Azure Databricks Medallion Data Platform
Raw events enter ADLS Gen2, undergo PySpark Medallion transformation (Bronze raw -> Silver sanitized -> Gold dimensional), and are exposed via Delta tables to analytical consumers.
Batch files and streaming events land in ADLS Gen2 with metadata envelopes (ingestion timestamp, source filename).
Strict tenant isolation and atomic data boundaries enforced at both gateway validation and persistence/table tiers.
Every stage emits structured trace contexts (OpenTelemetry / correlation IDs) for distributed debugging and latency profiling.
Key Engineering Decisions
Delta Lake format over plain Parquet files
Enabled ACID transactions, atomic MERGE operations for upserts, and time-travel rollbacks during debugging.
Requires scheduled OPTIMIZE and VACUUM maintenance jobs to prevent small file proliferation.
Cloud-native Managed Identities with Azure Key Vault
Removed all static storage credentials and database connection strings from Databricks cluster configurations.
Requires strict Azure RBAC role assignments across Service Principals and Key Vault access policies.
Measured System Results & Stability Guarantees
In accordance with our engineering verification policy, we document verified technical benchmarks and architectural milestones rather than unverifiable marketing claims.
Data Engineering & Lakehouse Platforms
Explore our full deliverables, tech stack, and engagement models for this capability.
Facing a Similar Engineering Challenge?
Whether you need to decouple a monolith, deploy an Azure Databricks Medallion lakehouse, or author custom Airbyte connectors, let's evaluate your technical requirements.